

The Legend of Mark: Why Your Tests Should Be Your Best Documentation
Imagine this: you join a new software project. You clone the repository, get everything running, and start looking through the code. Pretty quickly, you run into questions about how certain business logic is supposed to behave, especially in edge cases.
So you ask someone on the team how an important flow works.
The answer?
“Mark knows.”
There’s just one problem: Mark left the company three months ago.
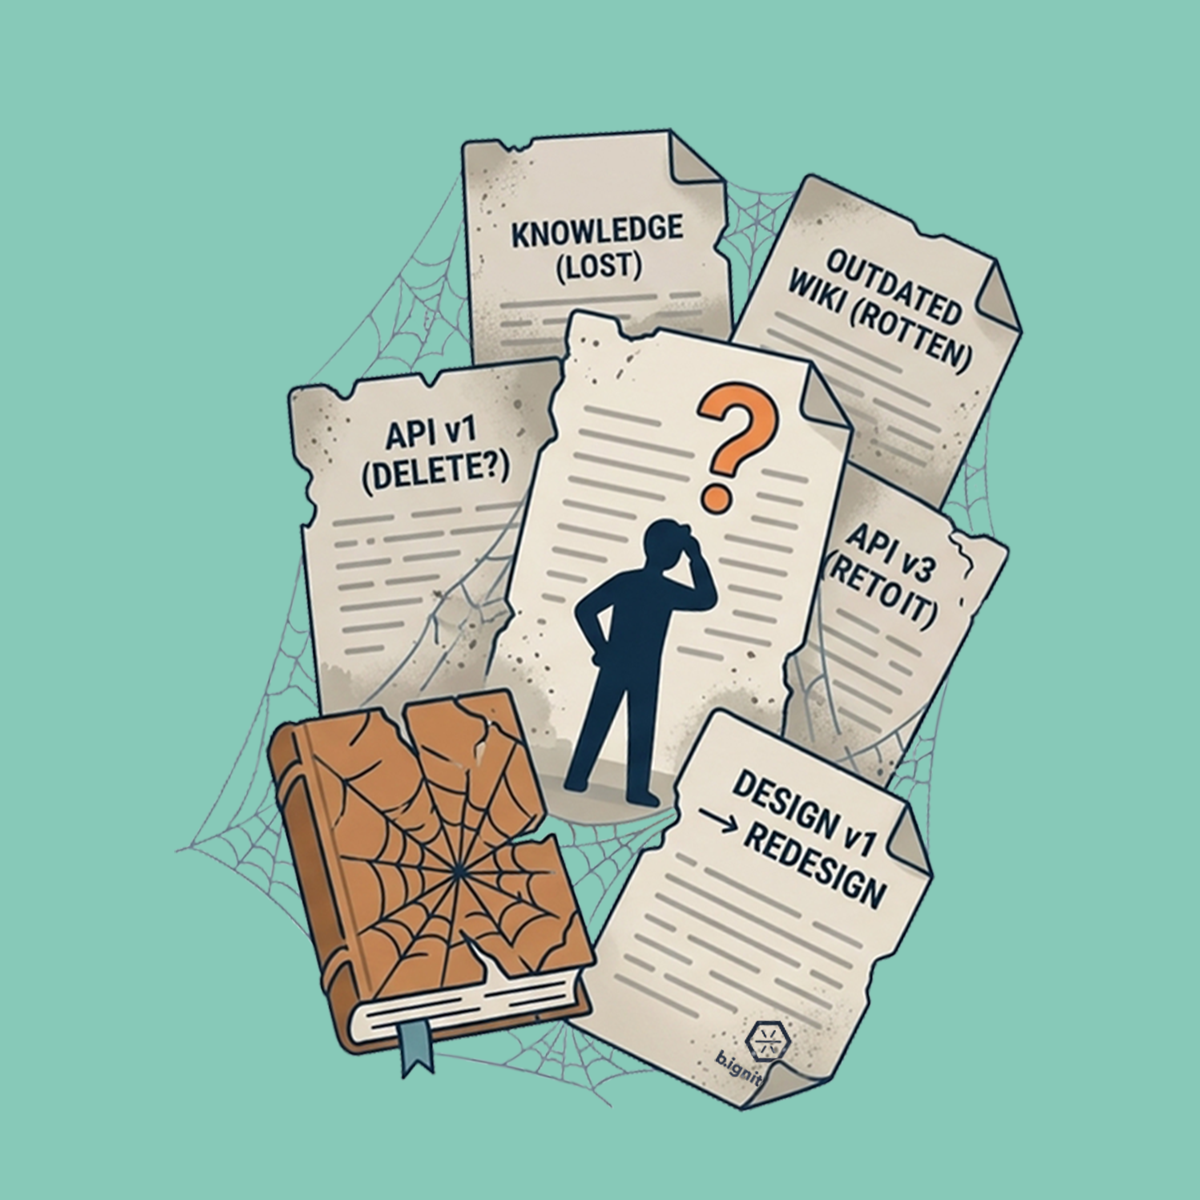
So you move on to Confluence. There, you find a page that hasn’t been updated in years. It mentions API endpoints that no longer exist and designs that have already been changed twice.
Sounds familiar?
This happens a lot in software development. Over time, the knowledge about how an application actually works slowly disappears. Some of it ends up in outdated documentation, and some of it simply leaves the company when people move on.
But there is one thing in your codebase that is constantly being updated and, ideally, runs every day: your test suite.
Blackbox Testing vs. Blackbox Code
In QA, we often talk about blackbox testing. We test an application from the outside, just like a real user would. This is useful because it allows us to test the actual user experience without worrying too much about how things are implemented internally.
But beware, it gets tricky when our tests become black boxes themselves.
You open a test and find a bunch of generic selectors, magic numbers, and test data that seems to come from somewhere else. You can see what the test is doing, but you have no idea why it is doing it.
For example, if a test uses a database seeder hidden somewhere in the project, a developer looking at the test might have to dig through several files just to understand the starting state of the test.
And when the test fails? Good luck figuring out what it was actually trying to prove.
Write Tests Like a Story
A good end-to-end test should be easy to follow. Ideally, you should be able to read it almost like a small story:
This is the starting situation.
This is what the user does.
And this is what we expect to happen.
That starts with making the initial state visible.
```javascript
it('blocks checkout', () => {
  seedCart(); // what's in here? who knows
  cy.visit('/checkout');
  cy.get('.btn-1').click();
  cy.get('.err').should('exist');
});
```
Instead of hiding important state or test data somewhere else, make it clear in the test itself. When someone opens the file six months from now, they should be able to understand the setup without having to go on a small archaeological expedition through the codebase.
```javascript
it('prevents checkout when cart total exceeds available credit', () => {
  // Given: a cart that exceeds the user's credit limit
  cy.setLocalStorage('cart', JSON.stringify({
    items: [{ id: 'sku-42', price: 500, qty: 1 }],
    creditLimit: 100,
  }));

  // When: the user tries to check out
  cy.visit('/checkout');
  cy.get('[data-cy="place-order"]').click();

  // Then: they see a clear rejection, not a silent failure
  cy.get('[data-cy="checkout-error"]')
    .should('be.visible')
    .and('contain.text', 'This order exceeds your available credit');
});
```
Network mocking can help with this too. Tools like cy.intercept() aren't just useful for making tests faster or more reliable. They can also make the expected behaviour of the application much clearer.
For example, if a test explicitly mocks a 401 response and checks how the application handles it, the test tells you something important about the system:
When the user is no longer authenticated, this is what we expect the application to do.
```javascript
it('redirects to login when the session has expired', () => {
  // Document the exact scenario: an authenticated request that suddenly gets a 401
  cy.intercept('GET', '/api/user/profile', {
    statusCode: 401,
    body: { error: 'Token expired' },
  }).as('expiredSession');

  cy.visit('/dashboard');
  cy.wait('@expiredSession');

  // This IS the spec for "what happens when auth is lost"
  cy.url().should('include', '/login');
  cy.get('[data-cy="session-expired-banner"]')
    .should('be.visible')
    .and('contain.text', 'Your session has expired. Please log in again.');
});
```
That's valuable information. And unlike a wiki page, the test is actually executed.
The same applies to test names and selectors. A descriptive test title can tell you what behaviour we're testing before you even read the code. Clear selectors make it easier to understand what the test is interacting with.
The goal shouldn't just be to get good test coverage.
The goal should be to make the tests understandable.
Tests as Living Documentation
When tests are written this way, they become more than just a safety net for developers.
They become documentation that actually lives alongside the code.
A wiki can become outdated. A Confluence page can be forgotten. And Mark can leave the company.
But a test that runs every day is much harder to ignore.
When the application changes, the test either keeps passing and confirms that the documented behaviour is still valid, or it fails and forces us to take a look.
```javascript
// Bad: tells you nothing without opening the file
it('test 12', () => {
  cy.get('#el-9821').click();
});

// Good: the title + selectors explain the behavior before you read the body
it('allows an admin to permanently delete a draft post', () => {
  cy.get('[data-cy="delete-draft-button"]').click();
  cy.get('[data-cy="confirm-permanent-deletion-dialog"]')
    .find('[data-cy="confirm-delete-button"]')
    .click();

  cy.get('[data-cy="toast-message"]')
    .should('be.visible')
    .and('contain.text', 'Draft deleted');
});
```
That makes well-written tests a pretty powerful form of documentation: they don't just tell you how the system is supposed to work. They continuously check that it still works that way.
And honestly, I'd much rather ask the test suite than ask Mark.